🔒 Building a PII Guardrail Proxy for Cloud LLM Calls
A local model classifies every prompt before it leaves the cluster. If it’s sensitive, it’s blocked. If it’s clean, it goes to NVIDIA NIM. 150 lines of FastAPI, deployed on k3s.
A local model classifies every prompt before it leaves the cluster. If it’s sensitive, it’s blocked. If it’s clean, it goes to NVIDIA NIM. 150 lines of FastAPI, deployed on k3s.
Replace PII with semantically realistic fakes before sending to a cloud LLM, then restore the originals from the response. Started with a general model and prompt engineering — then upgraded to a purpose-built 1.7B fine-tune via Ollama.
llama.cpp’s inference server ships a /metrics endpoint. One flag, Prometheus scraping, a Grafana dashboard loaded via ConfigMap sidecar — AI observability without a proxy layer.
A CPU-only self-hosted LLM stack running on k3s: llama.cpp as the inference server, Open WebUI as the chat interface, deployed as a single Git push.
Rebooting a misbehaving node feels productive. It isn’t. You’re erasing your evidence and skipping the lesson.
No open ports. Real TLS at home. One IngressRoute per app. This is the networking setup I landed on after ruling out everything that required a compromise.
I wanted to learn production-grade Kubernetes patterns without breaking production. One node, a full GitOps stack, and a hard rule: no manual kubectl after bootstrap.
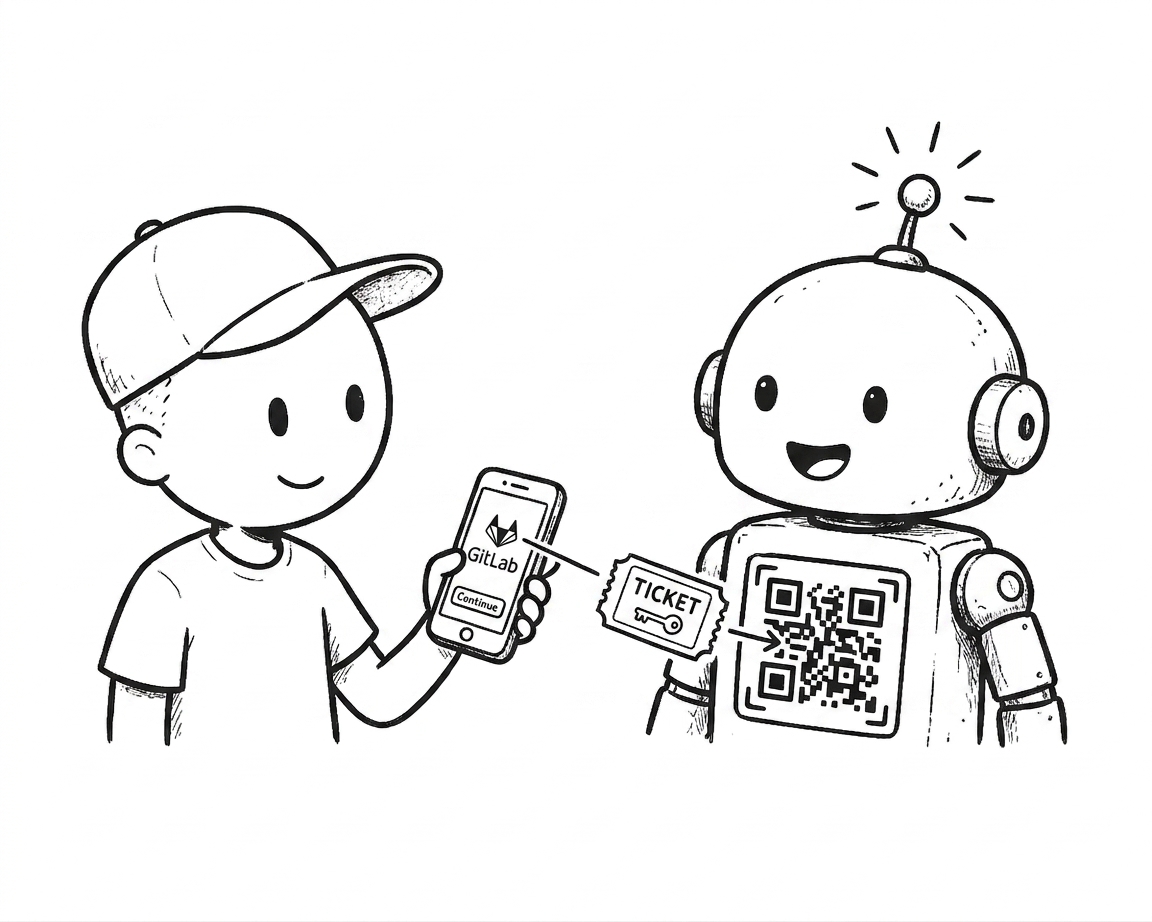
My homelab uses oauth2-proxy for GitLab SSO. I wanted a QR code login for the TV dashboard. Two days and four complete rewrites later, I knew more about oauth2-proxy’s session format than I ever planned to.